
Criteria for using RAG in enterprise systems
15 September 2025 · 3 min read
Retrieval-Augmented Generation combines a language model with search over an organisation’s own documents. The article sets out when RAG is justified, when a simpler solution is enough and which risks from the OWASP list for LLM applications concern the document index.

Retrieval-Augmented Generation (RAG) was described by Patrick Lewis and co-authors in a paper accepted at NeurIPS 2020. In that approach a generative model uses knowledge stored in its parameters together with an external document index searched for every query.
In an enterprise system RAG makes it possible to answer from policies, contracts and technical documentation without retraining the model. Not every user question needs a language model, however, so the article sets out decision criteria (author’s analysis).
In this article
Conditions that justify RAG
RAG makes sense when the knowledge needed for an answer changes more often than it is worth changing the model, and the answer must point to the document it comes from. This applies above all to unstructured collections such as procedures, contracts, technical notes and correspondence, which users ask about in their own words.
The value of such a use case lies in shortening the path to the right passage and letting a person check it (author’s analysis).
Simpler solutions for some questions
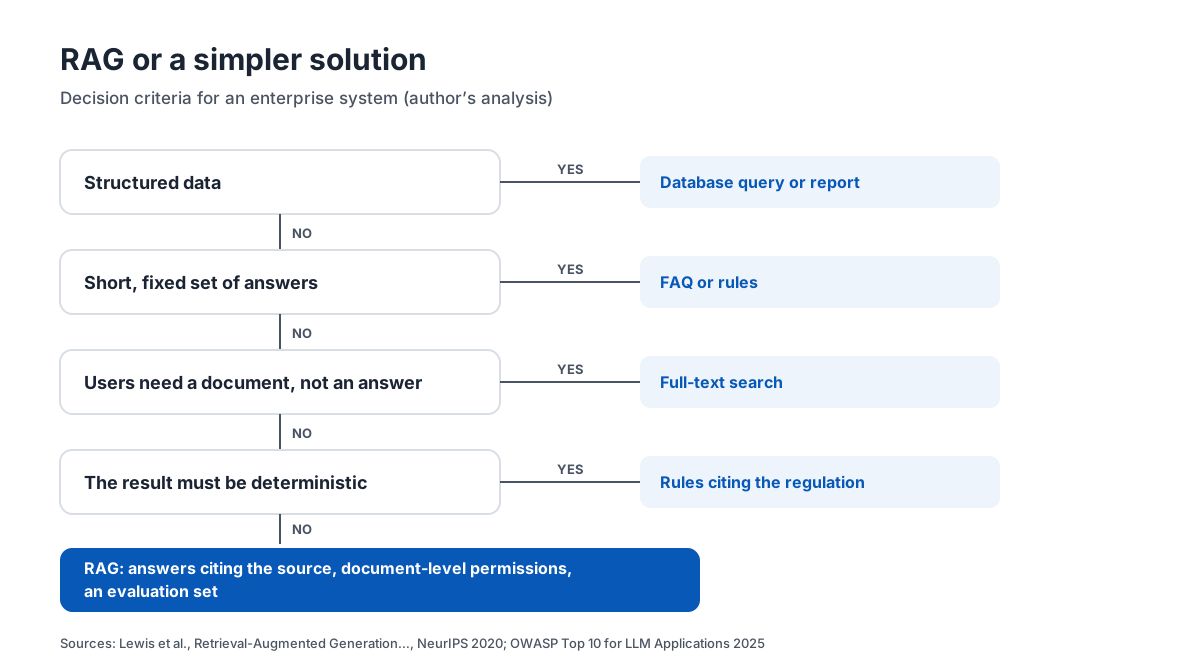
If the data is structured, a database query or a report gives the answer. A short, fixed set of answers fits in an FAQ or in rules. When users look for a document rather than an answer, full-text search is enough. If the result must be deterministic, for example for amounts and deadlines, rules citing the source work better.
RAG remains the option for questions that pass none of these filters (author’s analysis).
Risks of the document index
The OWASP Top 10 for LLM Applications 2025 contains three entries of particular relevance to RAG. LLM08 Vector and Embedding Weaknesses concerns weaknesses in embeddings and the vector index. LLM01 Prompt Injection also covers instructions hidden in document content that reaches the model’s context. LLM02 Sensitive Information Disclosure concerns revealing information the person asking should not see.
In practice this means checking document permissions at search time and treating document content strictly as data for the model (author’s analysis).
Measuring answer quality
Before deployment it is worth preparing a set of test questions with the expected source document for each. The measure is the share of answers that point to the right source, together with the system’s behaviour when no source exists: declining to answer is then the correct result. The same set is run after every change to the model, the document chunking or the index (author’s analysis).
Sources
- P. Lewis et al., Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks, NeurIPS 2020 – arxiv.org/abs/2005.11401
- OWASP, Top 10 for LLM Applications 2025 – genai.owasp.org/llm-top-10/
Key takeaways
- RAG is justified when knowledge changes often and the answer must point to a source document.
- Structured data, a fixed set of answers and document search are served by simpler tools than a language model.
- Document permissions must be checked at search time, because the content reaches the model’s context.
- A test set with expected sources makes it possible to compare quality before and after a system change.
Next steps
- Grouping user questions according to the decision diagram and choosing a tool for each group.
- Attaching source, date and permission metadata to every document in the index.
- Preparing a set of test questions with the expected source document.
- Reviewing the OWASP risks LLM01, LLM02 and LLM08 for the planned solution.